Filter by type:
Filter by tags:

qwen3.8-27b-dflash2
Qwen3.8-27B with DFlash 2 speculative decoding on the llama.cpp backend.
DFlash 2 is a small drafter model that guesses a whole block of upcoming tokens in one pass. It keeps several candidates for each position and picks one coherent path through them. The full Qwen3.8-27B model then checks the guessed tokens in a single step and keeps the ones it agrees with, so generation is faster and the output is the same as without the drafter: greedy output is identical, and sampling keeps the target's distribution. The drafter is not a standalone model; it only runs paired with the target.
This entry downloads the Q4_K_M target (about 19 GB) and the Q4_K_M drafter (about 1.1 GB). Any standard Qwen3.8-27B GGUF quantization can serve as the target. The block size is set to 7 draft tokens. Flash attention is required and is enabled. A GPU is recommended. This entry is text only.
Repository: localaiLicense: apache-2.0

muse-glimmer-30b-dflash
Muse Glimmer's higher-quality dynamic K-quant GGUF with the official
quantized perception encoder and DFlash drafter. DFlash proposes blocks of
up to 16 tokens for the target to verify in parallel, accelerating output
without changing model quality. Flash attention is enabled for this path.
Repository: localaiLicense: apache-2.0
muse-glimmer-30b-17gb-dflash
Muse Glimmer's smaller 17 GB K-quant GGUF with the official quantized
perception encoder and DFlash drafter. This is the lowest-memory published
build that retains image understanding and block-speculative decoding.
Flash attention is enabled for the DFlash path.
Repository: localaiLicense: apache-2.0

laguna-s-2.1-dflash
Laguna S 2.1's 96 GB Q4_K_M target paired with Poolside's 2.2 GB BF16 DFlash drafter for speculative decoding. DFlash drafts a block of tokens per forward pass and accelerates generation without changing the target model's outputs. Flash attention is enabled because the DFlash path requires it.
License: OpenMDW 1.1.
Repository: localaiLicense: other
qwen3-4b-dflash
Qwen3-4B paired with its DFlash block-diffusion drafter for speculative decoding on the llama.cpp backend. This is the canonical DFlash pairing documented upstream (`z-lab/Qwen3-4B-DFlash` + `Qwen/Qwen3-4B`).
DFlash produces a whole block of draft tokens in a single forward pass and injects the target model's hidden states into the drafter's attention, which keeps the drafter tiny while making drafting GPU-friendly. The Q4_K_M file carries the full Qwen3-4B target; the ~0.5 GB Q8_0 drafter (`draft-dflash`) accelerates generation without changing the target's outputs. The drafter is not a standalone chat model: it only runs paired with the target, which is why both are bundled here.
Flash attention is required for DFlash and is enabled in this config. A GPU is recommended.
License: Apache 2.0 (Qwen3-4B target) / MIT (z-lab DFlash drafter).
Repository: localaiLicense: apache-2.0
qwen3.5-4b-dflash
Qwen3.5-4B paired with its DFlash block-diffusion drafter for speculative decoding on the llama.cpp backend.
DFlash produces a whole block of draft tokens in a single forward pass and injects the target model's hidden states into the drafter's attention, which keeps the drafter tiny while making drafting GPU-friendly. The Q4_K_M file carries the full Qwen3.5-4B target; the ~0.6 GB Q8_0 drafter (`draft-dflash`) accelerates generation without changing the target's outputs. The drafter is not a standalone chat model: it only runs paired with the target, which is why both are bundled here.
Flash attention is required for DFlash and is enabled in this config. A GPU is recommended.
License: Apache 2.0 (Qwen3.5-4B target) / MIT (z-lab DFlash drafter).
Repository: localaiLicense: apache-2.0
qwen3.5-9b-dflash
Qwen3.5-9B paired with its DFlash block-diffusion drafter for speculative decoding on the llama.cpp backend.
DFlash produces a whole block of draft tokens in a single forward pass and injects the target model's hidden states into the drafter's attention, which keeps the drafter tiny while making drafting GPU-friendly. The Q4_K_M file carries the full Qwen3.5-9B target; the ~1 GB Q8_0 drafter (`draft-dflash`) accelerates generation without changing the target's outputs. The drafter is not a standalone chat model: it only runs paired with the target, which is why both are bundled here.
Flash attention is required for DFlash and is enabled in this config. A GPU is recommended.
License: Apache 2.0 (Qwen3.5-9B target) / MIT (z-lab DFlash drafter).
Repository: localaiLicense: apache-2.0
qwen3.6-27b-dflash
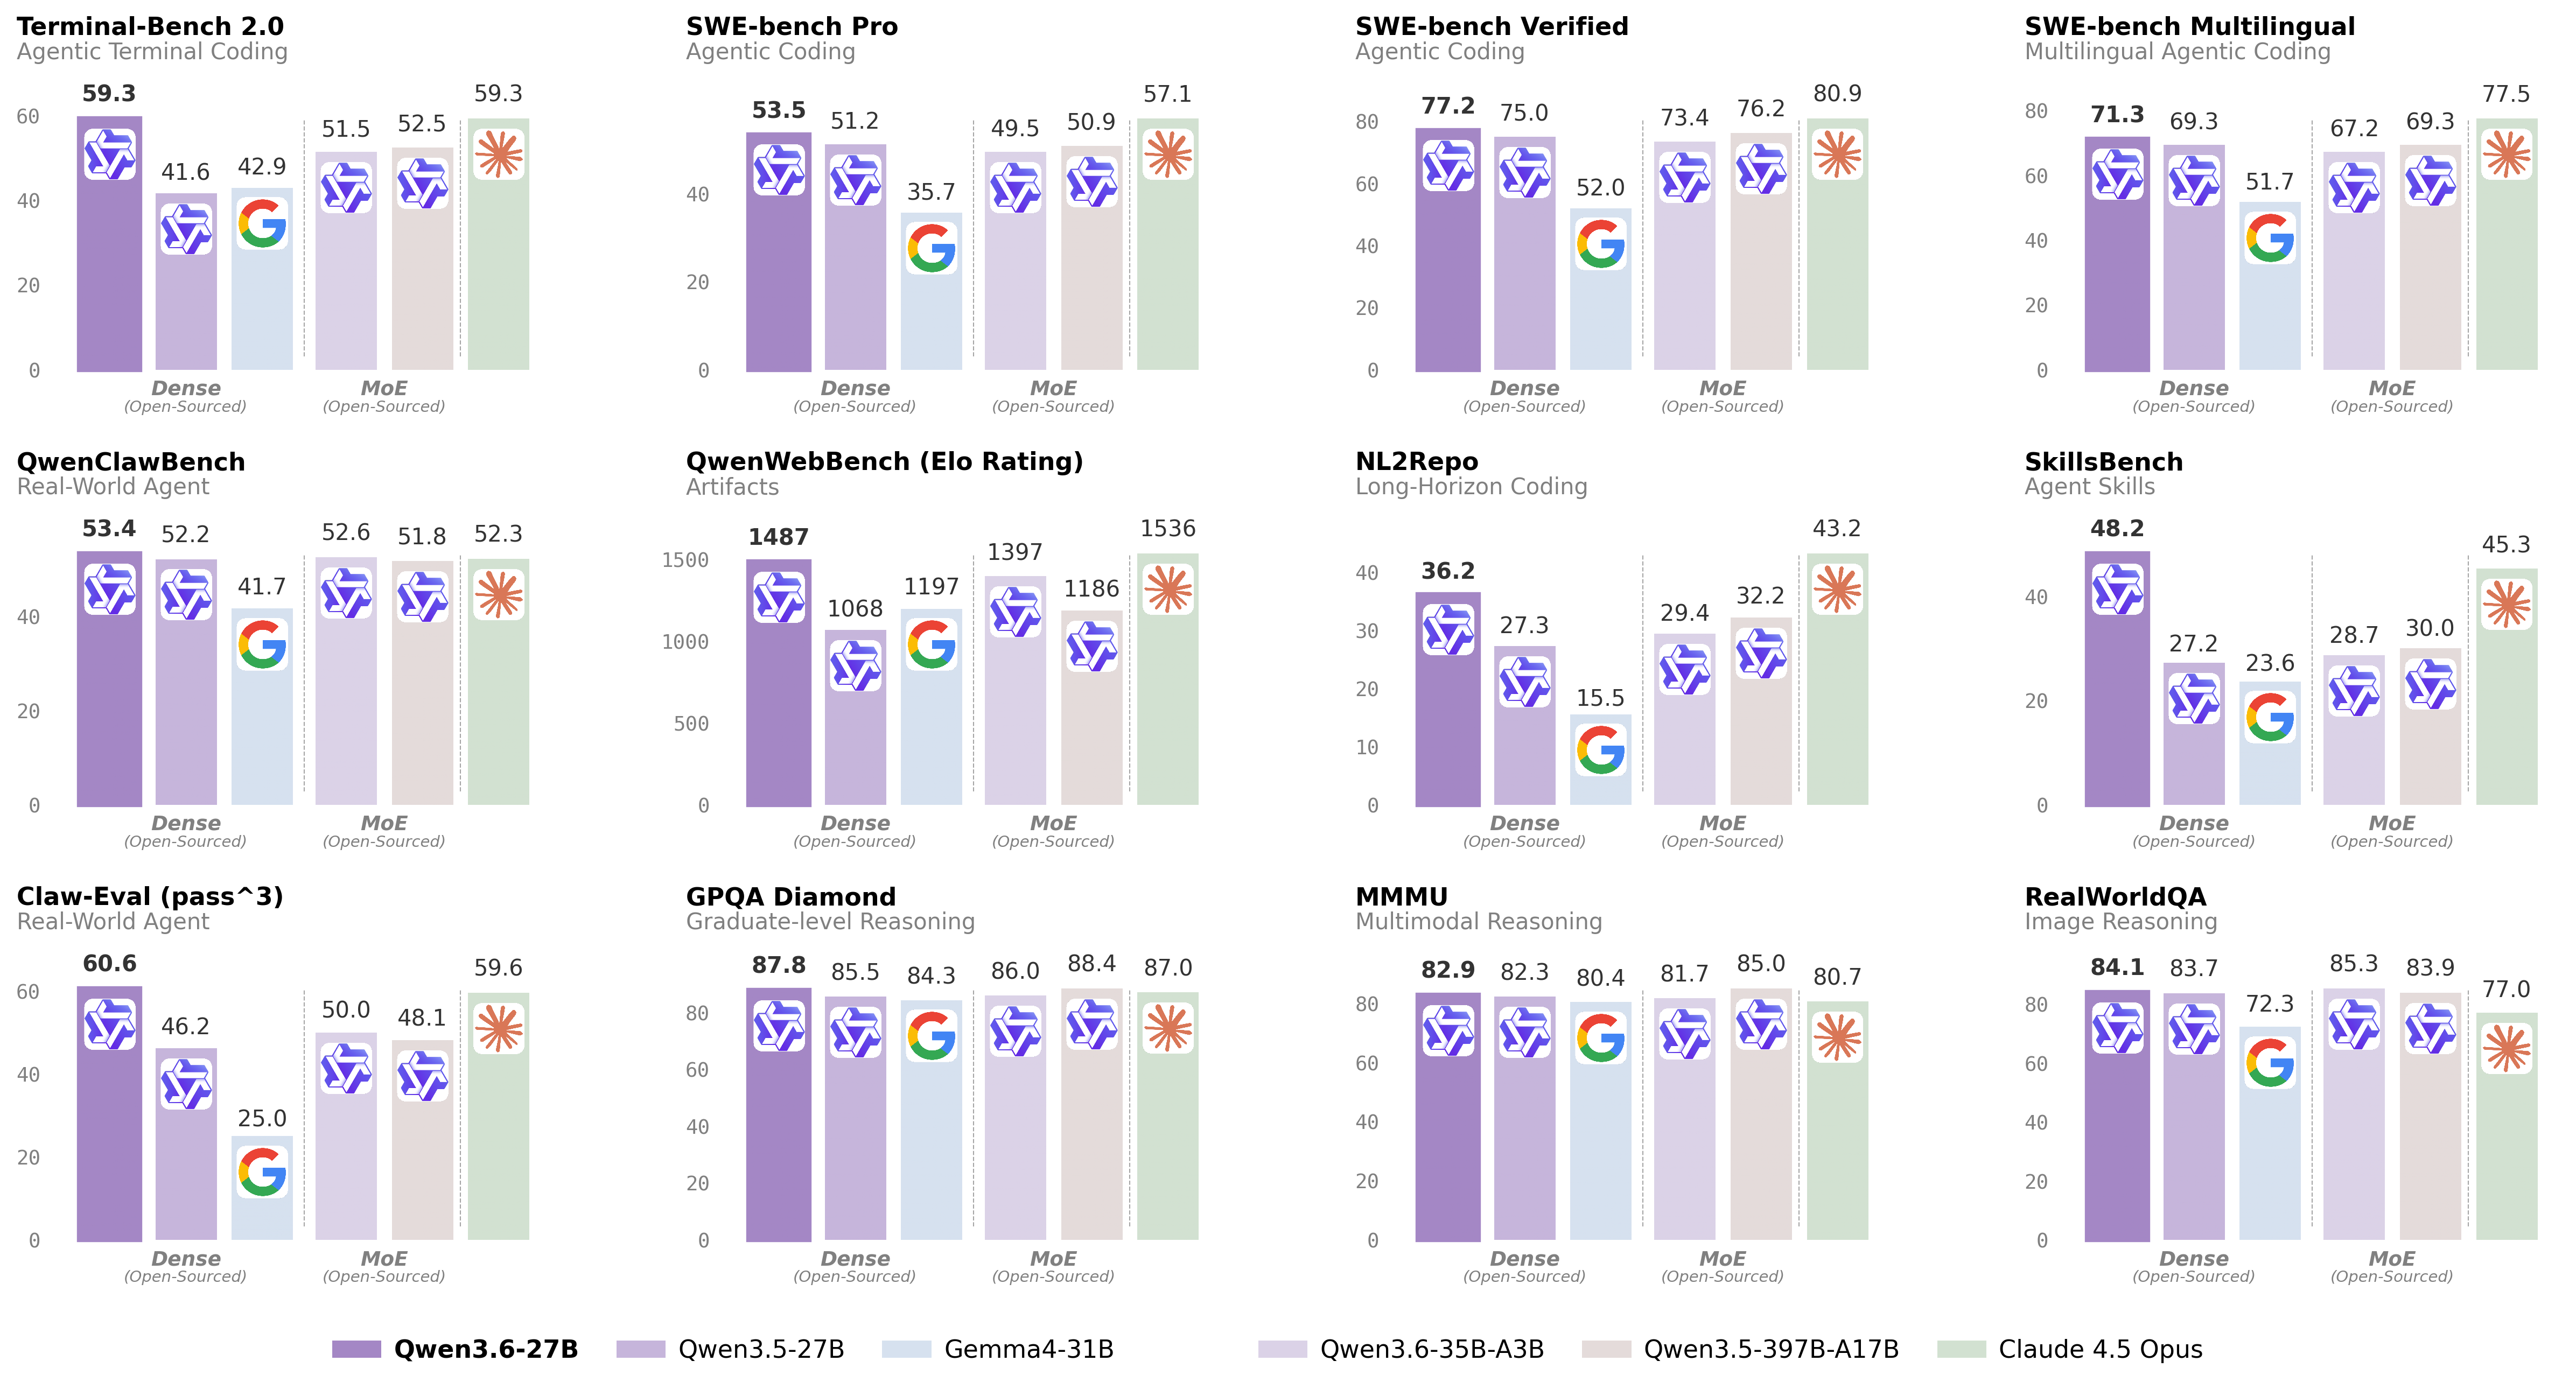
Qwen3.6-27B (dense) paired with its DFlash block-diffusion drafter for speculative decoding on the llama.cpp backend. DFlash gives its largest speedups on dense targets like this one.
DFlash produces a whole block of draft tokens in a single forward pass and injects the target model's hidden states into the drafter's attention, which keeps the drafter tiny while making drafting GPU-friendly. The Q4_K_M file carries the full Qwen3.6-27B target; the ~1.8 GB Q8_0 drafter (`draft-dflash`) accelerates generation without changing the target's outputs. The drafter is not a standalone chat model: it only runs paired with the target, which is why both are bundled here.
Flash attention is required for DFlash and is enabled in this config. A GPU is recommended.
License: Apache 2.0.
Repository: localaiLicense: apache-2.0
qwen3.6-35b-a3b-dflash
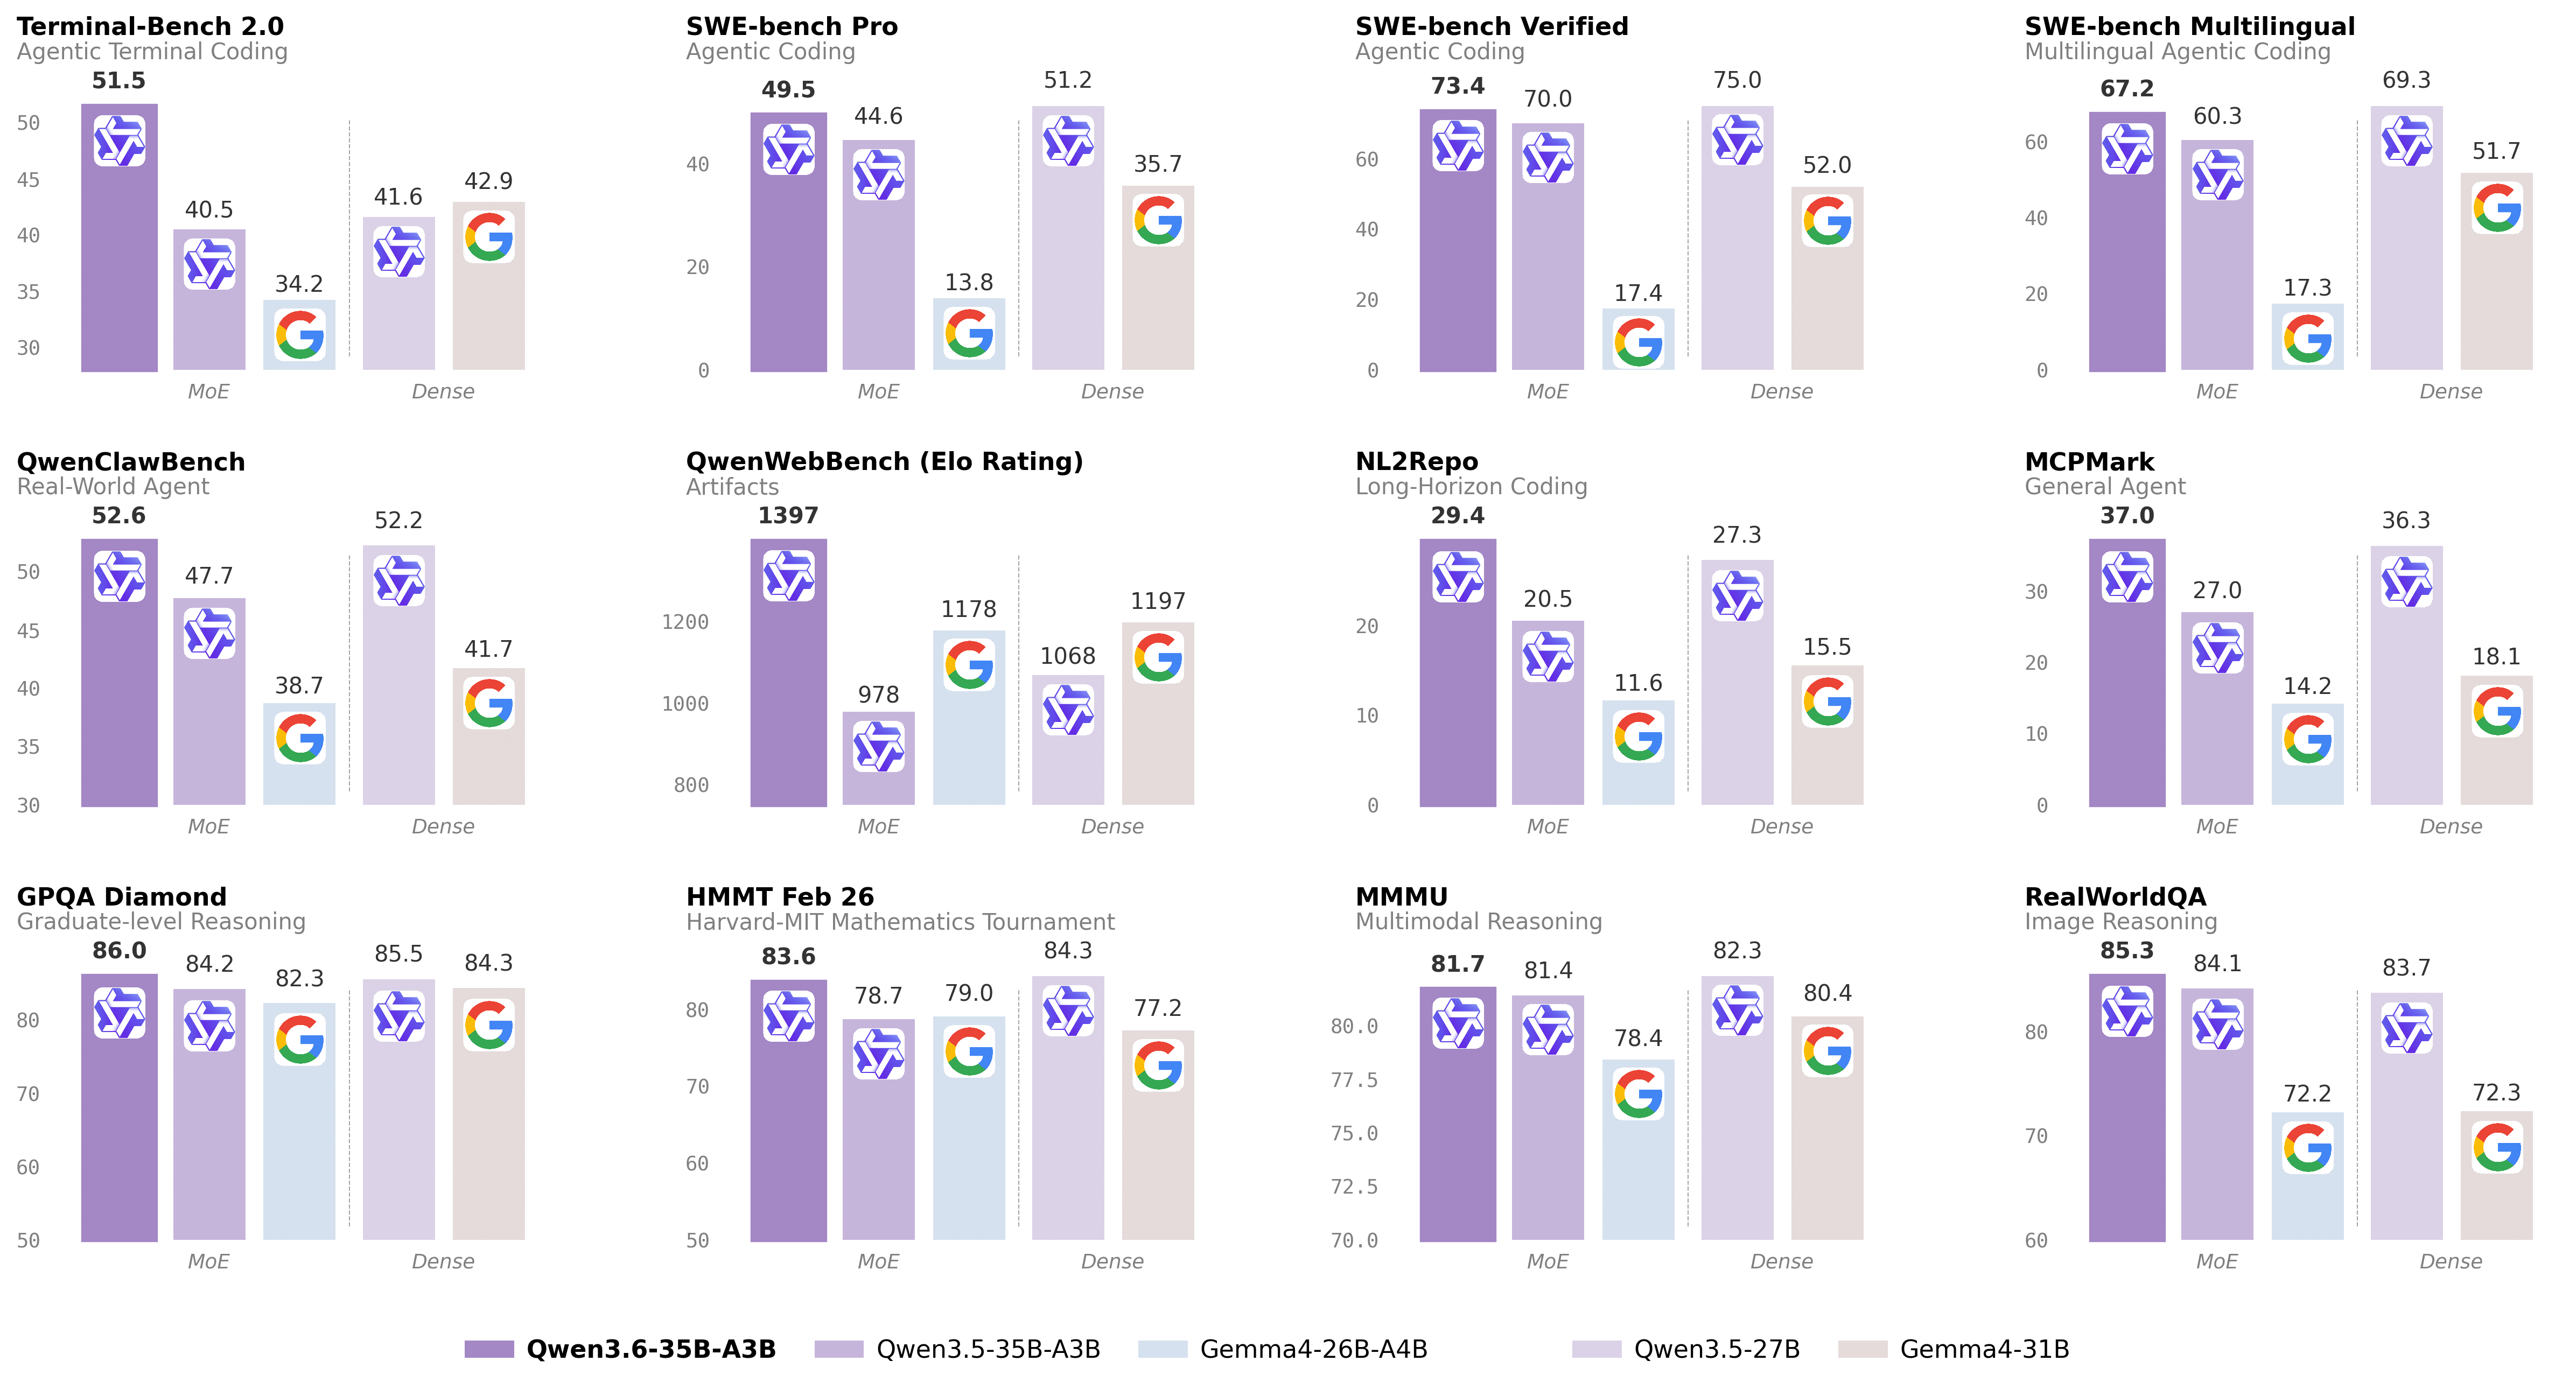
Qwen3.6-35B-A3B (Mixture-of-Experts, ~3B active per token) paired with its DFlash block-diffusion drafter for speculative decoding on the llama.cpp backend. DFlash speedups on MoE targets are smaller than on dense models, but still useful.
DFlash produces a whole block of draft tokens in a single forward pass and injects the target model's hidden states into the drafter's attention, which keeps the drafter tiny while making drafting GPU-friendly. The UD-Q4_K_M file carries the full Qwen3.6-35B-A3B target; the ~0.4 GB Q8_0 drafter (`draft-dflash`) accelerates generation without changing the target's outputs. The drafter is not a standalone chat model: it only runs paired with the target, which is why both are bundled here.
Flash attention is required for DFlash and is enabled in this config. A GPU is recommended.
License: Apache 2.0.
Repository: localaiLicense: apache-2.0
qwen3.8-27b-dflash2-exl3-vllm-cpp
Qwen3.8-27B EXL3 with its EXL3 DFlash2 companion, served by vllm.cpp. On
GB10 this pinned pair measured 48.7 tokens/s at a seven-token draft budget,
versus 16.7 tokens/s target-only, with token-identical greedy output.
LocalAI stages both complete Hugging Face repositories before load. The
content-addressed companion snapshot is passed to the backend as the draft
model, while the speculative method and seven-token budget remain fixed.
Repository: localai
qwen3.6-27b-nvfp4-dflash-vllm-cpp
Qwen3.6-27B NVFP4 on vllm.cpp with DFlash block-diffusion speculative
decoding: the fastest configuration of this model the engine ships.
Where MTP drafts one token at a time, DFlash drafts a whole 16-token block in
a single non-autoregressive pass from a separate 3.5 GB drafter, then the
target verifies the block in one step. At concurrency 1 that measures 2.9x
the throughput of the same weights with speculation off, and at or above
vLLM's own DFlash-on decode.
Both checkpoints are installed for you: the target as a revision-pinned
snapshot, the drafter into models/Qwen3.6-27B-DFlash, which is where the
backend looks when speculative_config.model names it. The drafter shares the
target's embed_tokens and lm_head, so the two are not independently
swappable.
Needs a Blackwell-class NVIDIA GPU and roughly 28 GB of weights in total.
Repository: localaiLicense: apache-2.0
qwen3.8-27b-efficientthink-q6-dflash
Qwen3.8-27B EfficientThink, a reasoning fine-tune by nerkyor, in
Q6_K GGUF format with the matching Q8 vision projector.
Enables DFlash speculative decoding with the publisher's Q8 draft.
Repository: localaiLicense: apache-2.0
qwen3.8-27b-efficientthink-q8-dflash
Qwen3.8-27B EfficientThink, a reasoning fine-tune by nerkyor, in
Q8_0 GGUF format with the matching Q8 vision projector.
Enables DFlash speculative decoding with the publisher's Q8 draft.
Repository: localaiLicense: apache-2.0