Model Gallery

197 models from 1 repositories

Filter by type:

Filter by tags:

spark-x2.6-4b-q4
Spark-X2.6-4B is XHToken's 4B text model for conversation, reasoning, coding, and multilingual tasks. This build uses Q4_K_M GGUF weights, the embedded Jinja chat template, and a 32K-token default context.

Repository: localaiLicense: apache-2.0

spark-x2.6-4b-q8
Spark-X2.6-4B is XHToken's 4B text model for conversation, reasoning, coding, and multilingual tasks. This build uses Q8_0 GGUF weights, the embedded Jinja chat template, and a 32K-token default context.

Repository: localaiLicense: apache-2.0

ornith-1.5-122b-ud-q4-k-xl
Ornith 1.5 122B is a Qwen3.5 mixture-of-experts model for reasoning, coding, and tool use. This UD-Q4_K_XL GGUF build includes the F16 vision projector for image input and uses an 8,192-token default context.

Repository: localaiLicense: mit

ornith-1.5-122b-q8
Ornith 1.5 122B is a Qwen3.5 mixture-of-experts model for reasoning, coding, and tool use. This Q8_0 GGUF build includes the F16 vision projector for image input and uses an 8,192-token default context.

Repository: localaiLicense: mit

gemma-4-e2b-it-artemis-q3-k-l
TurinTech Artemis Q3_K_L quantization of Gemma 4 E2B from Google's QAT checkpoint, for local chat and tool calls. Accepts image input through the bundled F16 vision projector. Uses the embedded chat template and an 8192-token context. Thinking is on by default.

Repository: localaiLicense: apache-2.0

gemma-4-e2b-it-artemis-q3-k-m
TurinTech Artemis Q3_K_M quantization of Gemma 4 E2B from Google's QAT checkpoint, for local chat and tool calls. Accepts image input through the bundled F16 vision projector. Uses the embedded chat template and an 8192-token context. Thinking is on by default.

Repository: localaiLicense: apache-2.0

gemma-4-e2b-it-artemis-iq3-xxs
TurinTech Artemis IQ3_XXS quantization of Gemma 4 E2B from Google's QAT checkpoint, for local chat and tool calls. Accepts image input through the bundled F16 vision projector. Uses the embedded chat template and an 8192-token context. Thinking is on by default.

Repository: localaiLicense: apache-2.0

gemma-4-e2b-it-artemis-iq2-m
TurinTech Artemis IQ2_M quantization of Gemma 4 E2B from Google's QAT checkpoint, for local chat and tool calls. Accepts image input through the bundled F16 vision projector. Uses the embedded chat template and an 8192-token context. Thinking is on by default.

Repository: localaiLicense: apache-2.0

gemma-4-e4b-it-artemis-q4-0
TurinTech Artemis Q4_0 quantization of Gemma 4 E4B from Google's QAT checkpoint, for local chat, reasoning, and tool use. Accepts image input through the bundled F16 vision projector. Uses the embedded chat template and an 8192-token context. Thinking is on by default.

Repository: localaiLicense: apache-2.0

gemma-4-e4b-it-artemis-iq3-m
TurinTech Artemis IQ3_M quantization of Gemma 4 E4B from Google's QAT checkpoint, for local chat, reasoning, and tool use. Accepts image input through the bundled F16 vision projector. Uses the embedded chat template and an 8192-token context. Thinking is on by default.

Repository: localaiLicense: apache-2.0

gemma-4-e4b-it-artemis-q3-k-m
TurinTech Artemis Q3_K_M quantization of Gemma 4 E4B from Google's QAT checkpoint, for local chat, reasoning, and tool use. Accepts image input through the bundled F16 vision projector. Uses the embedded chat template and an 8192-token context. Thinking is on by default.

Repository: localaiLicense: apache-2.0

diplodocus-preview-q4
Diplodocus preview 4 is OsaurusAI's K2 Horizon 7B fine-tune for documents, spreadsheets, and tool-assisted tasks. This Q4_K_M GGUF build uses the embedded chat template and enables reasoning by default. Applications must provide the tools; the model download does not include workspace tools.

Repository: localaiLicense: apache-2.0

diplodocus-preview-q6
Diplodocus preview 4 is OsaurusAI's K2 Horizon 7B fine-tune for documents, spreadsheets, and tool-assisted tasks. This Q6_K GGUF build uses the embedded chat template and enables reasoning by default. Applications must provide the tools; the model download does not include workspace tools.

Repository: localaiLicense: apache-2.0

diplodocus-preview-q8
Diplodocus preview 4 is OsaurusAI's K2 Horizon 7B fine-tune for documents, spreadsheets, and tool-assisted tasks. This Q8_0 GGUF build uses the embedded chat template and enables reasoning by default. Applications must provide the tools; the model download does not include workspace tools.

Repository: localaiLicense: apache-2.0

atomic-minicpm-v-4.7-35b-a3b-uncensored-q4
AtomicChat's abliterated MiniCPM-V 4.7 is a 35B mixture-of-experts model with 3B active parameters for chat and image understanding. This AD-Q4_K-IQ4_XS build includes all 11 weight shards and the F16 vision projector, with the embedded chat template and a 32K-token default context.

Repository: localaiLicense: apache-2.0

atomic-minicpm-v-4.7-35b-a3b-uncensored-q6
AtomicChat's abliterated MiniCPM-V 4.7 is a 35B mixture-of-experts model with 3B active parameters for chat and image understanding. This AD-Q6_K build includes all 16 weight shards and the F16 vision projector, with the embedded chat template and a 32K-token default context.

Repository: localaiLicense: apache-2.0

huihui-qwen3.8-flash-next-abliterated-v2-q4
Huihui's second abliterated Qwen3.8-Flash-Next release adjusts the abliteration without modifying the experts. This vision-language mixture-of-experts model uses the publisher's UD-Q4_K_XL GGUF and BF16 projector for text chat and image input through llama.cpp. The default context is 32,768 tokens. Model weights use the Qwen Community License 1.0.

Repository: localaiLicense: other

huihui-qwen3.8-flash-next-abliterated-v2-iq4
Huihui's second abliterated Qwen3.8-Flash-Next release adjusts the abliteration without modifying the experts. This vision-language mixture-of-experts model uses the publisher's UD-IQ4_XS GGUF and BF16 projector for text chat and image input through llama.cpp. The default context is 32,768 tokens. Model weights use the Qwen Community License 1.0.

Repository: localaiLicense: other

qwen3.8-flash-next-uncensored
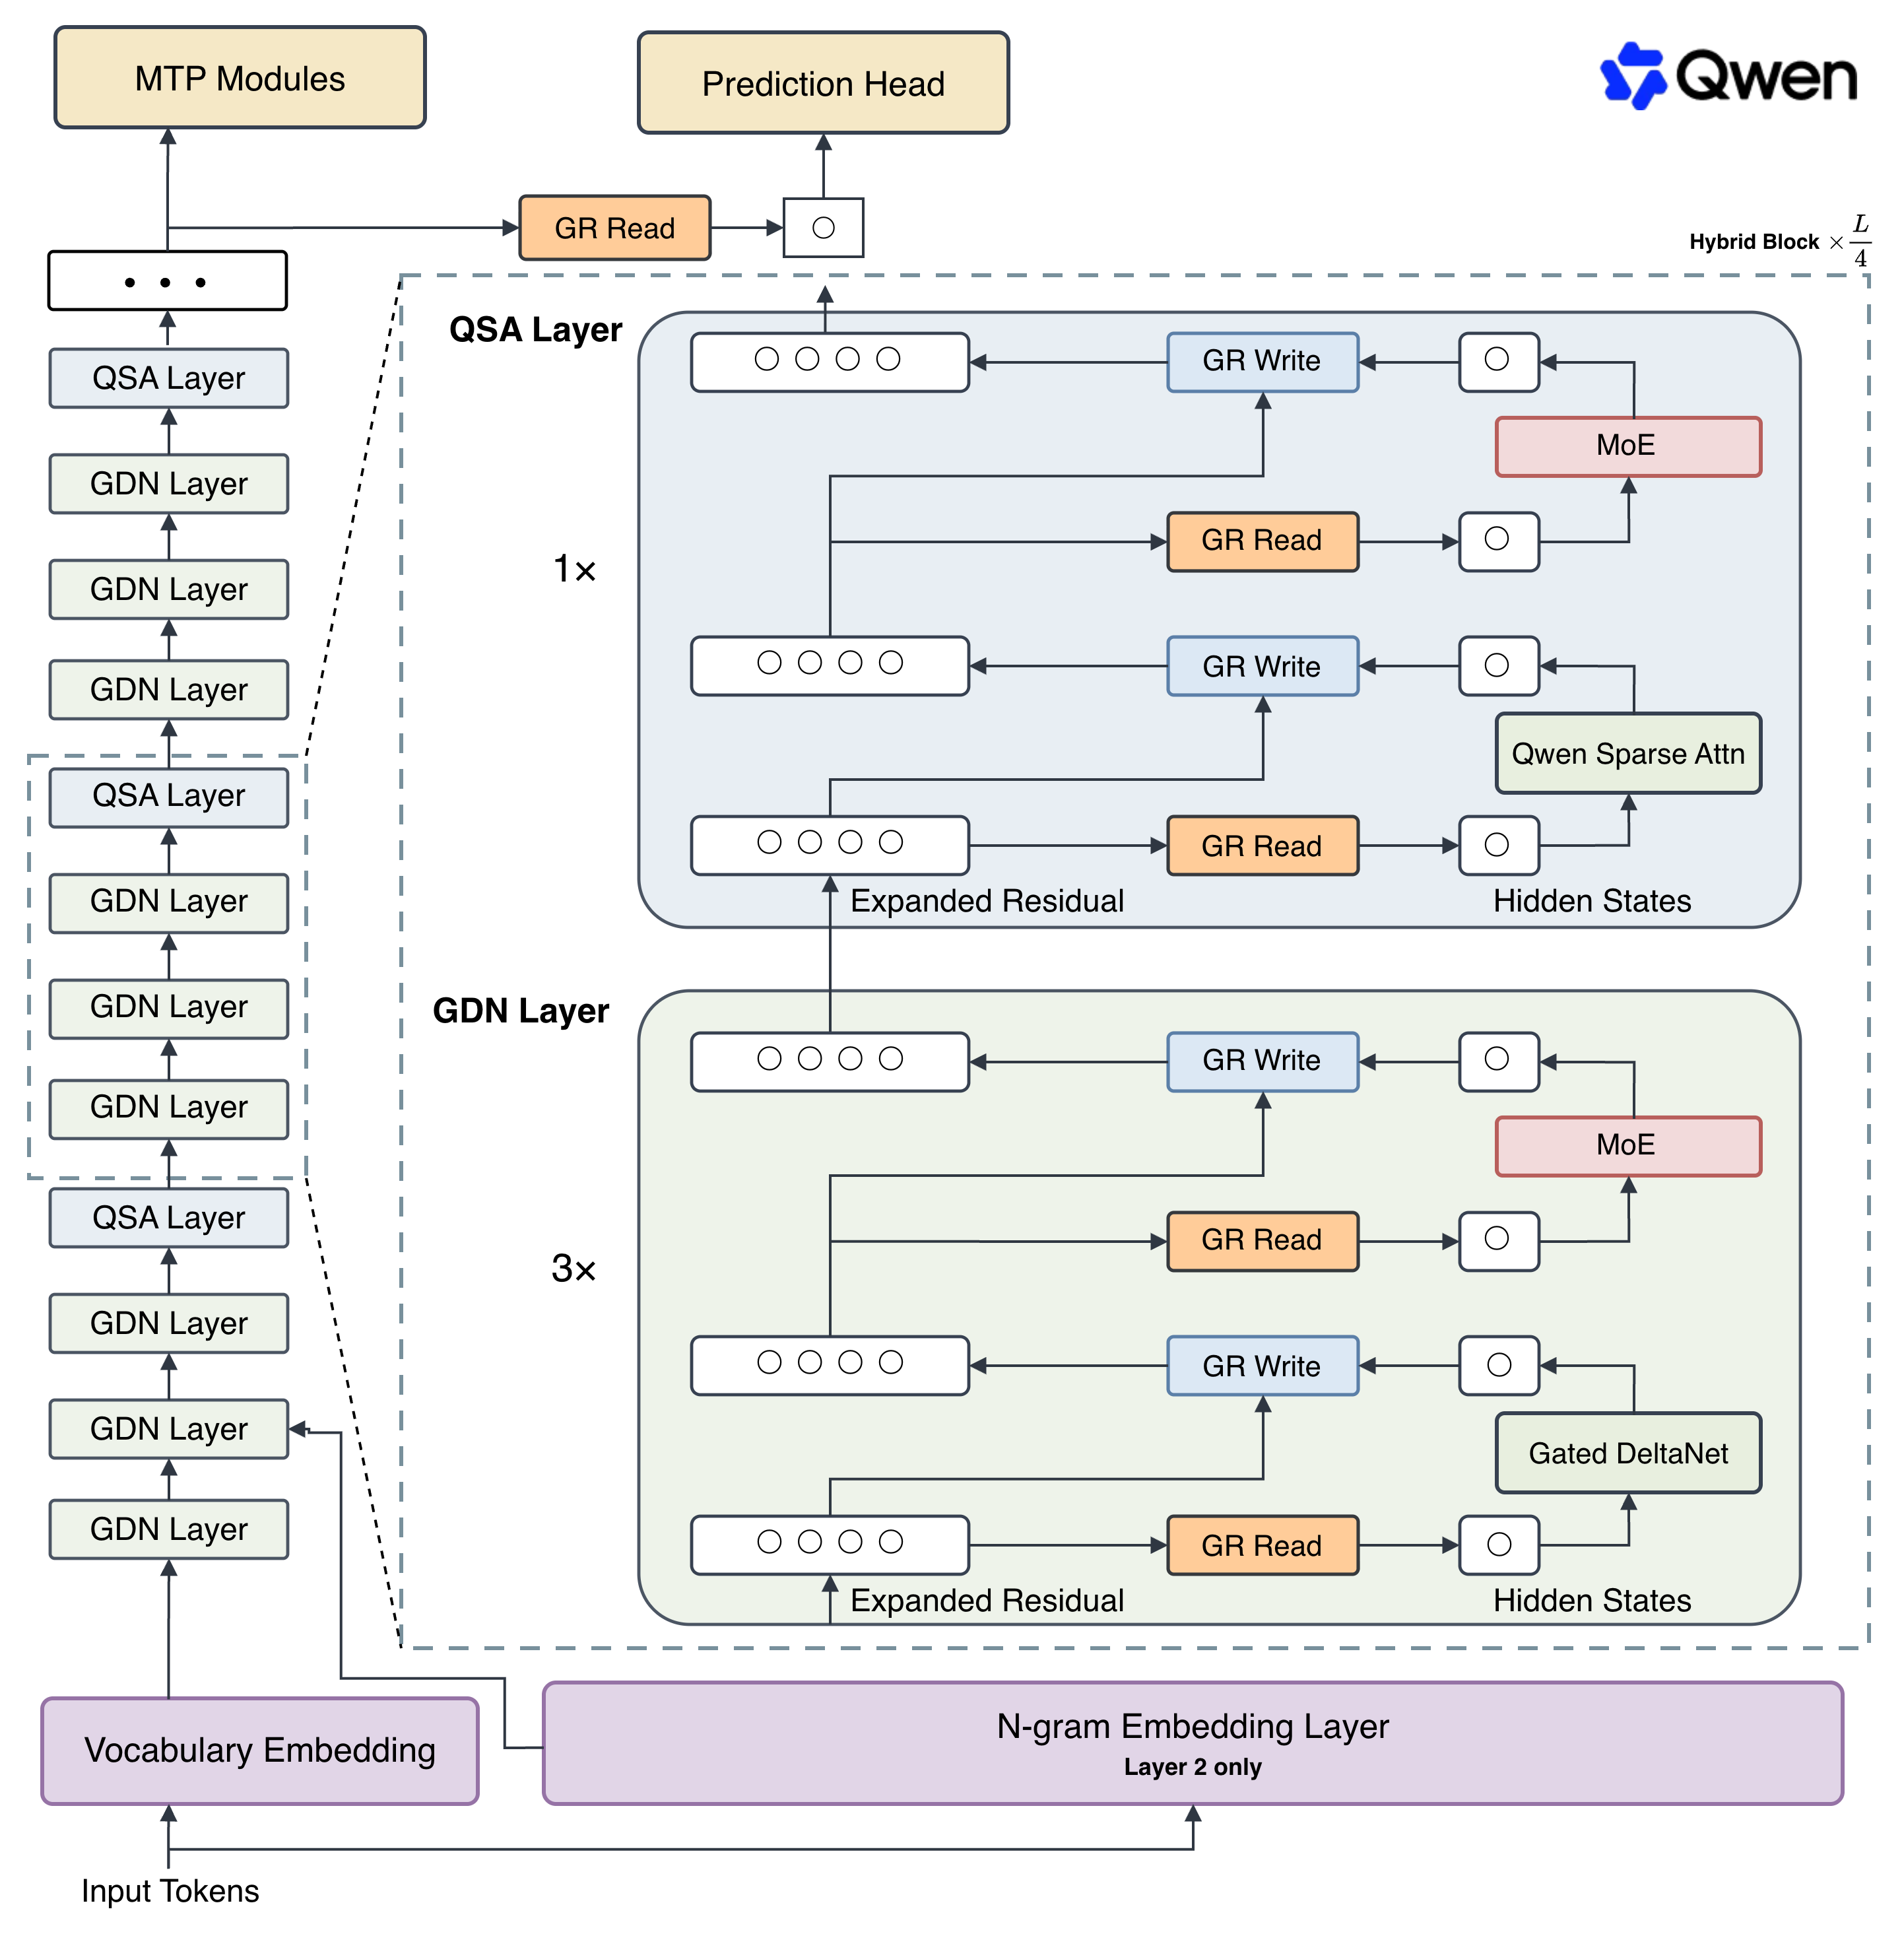
# Qwen3.8-Flash-Next > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > > In particular, **Qwen3.8-Flash** is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-Flash Overview. As the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next. ...

Repository: localaiLicense: apache-2.0

qwen3.8-27b-jumbo-fusion-q4
DavidAU's Jumbo Fusion edition of Qwen3.8-27B merges community fine-tunes and includes a custom template with reasoning and instruction modes. This Q4_K_M GGUF build supports text chat with a 32,768-token default context.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-jumbo-fusion-q8
DavidAU's Jumbo Fusion edition of Qwen3.8-27B merges community fine-tunes and includes a custom template with reasoning and instruction modes. This Q8_0 GGUF build supports text chat with a 32,768-token default context.

Repository: localaiLicense: apache-2.0

Page 1